AgentVQA
A Unified Benchmark for
Agentic Visual Understanding
1 University of Maryland, College Park · 2 Princeton University
 Dataset
About AgentVQA
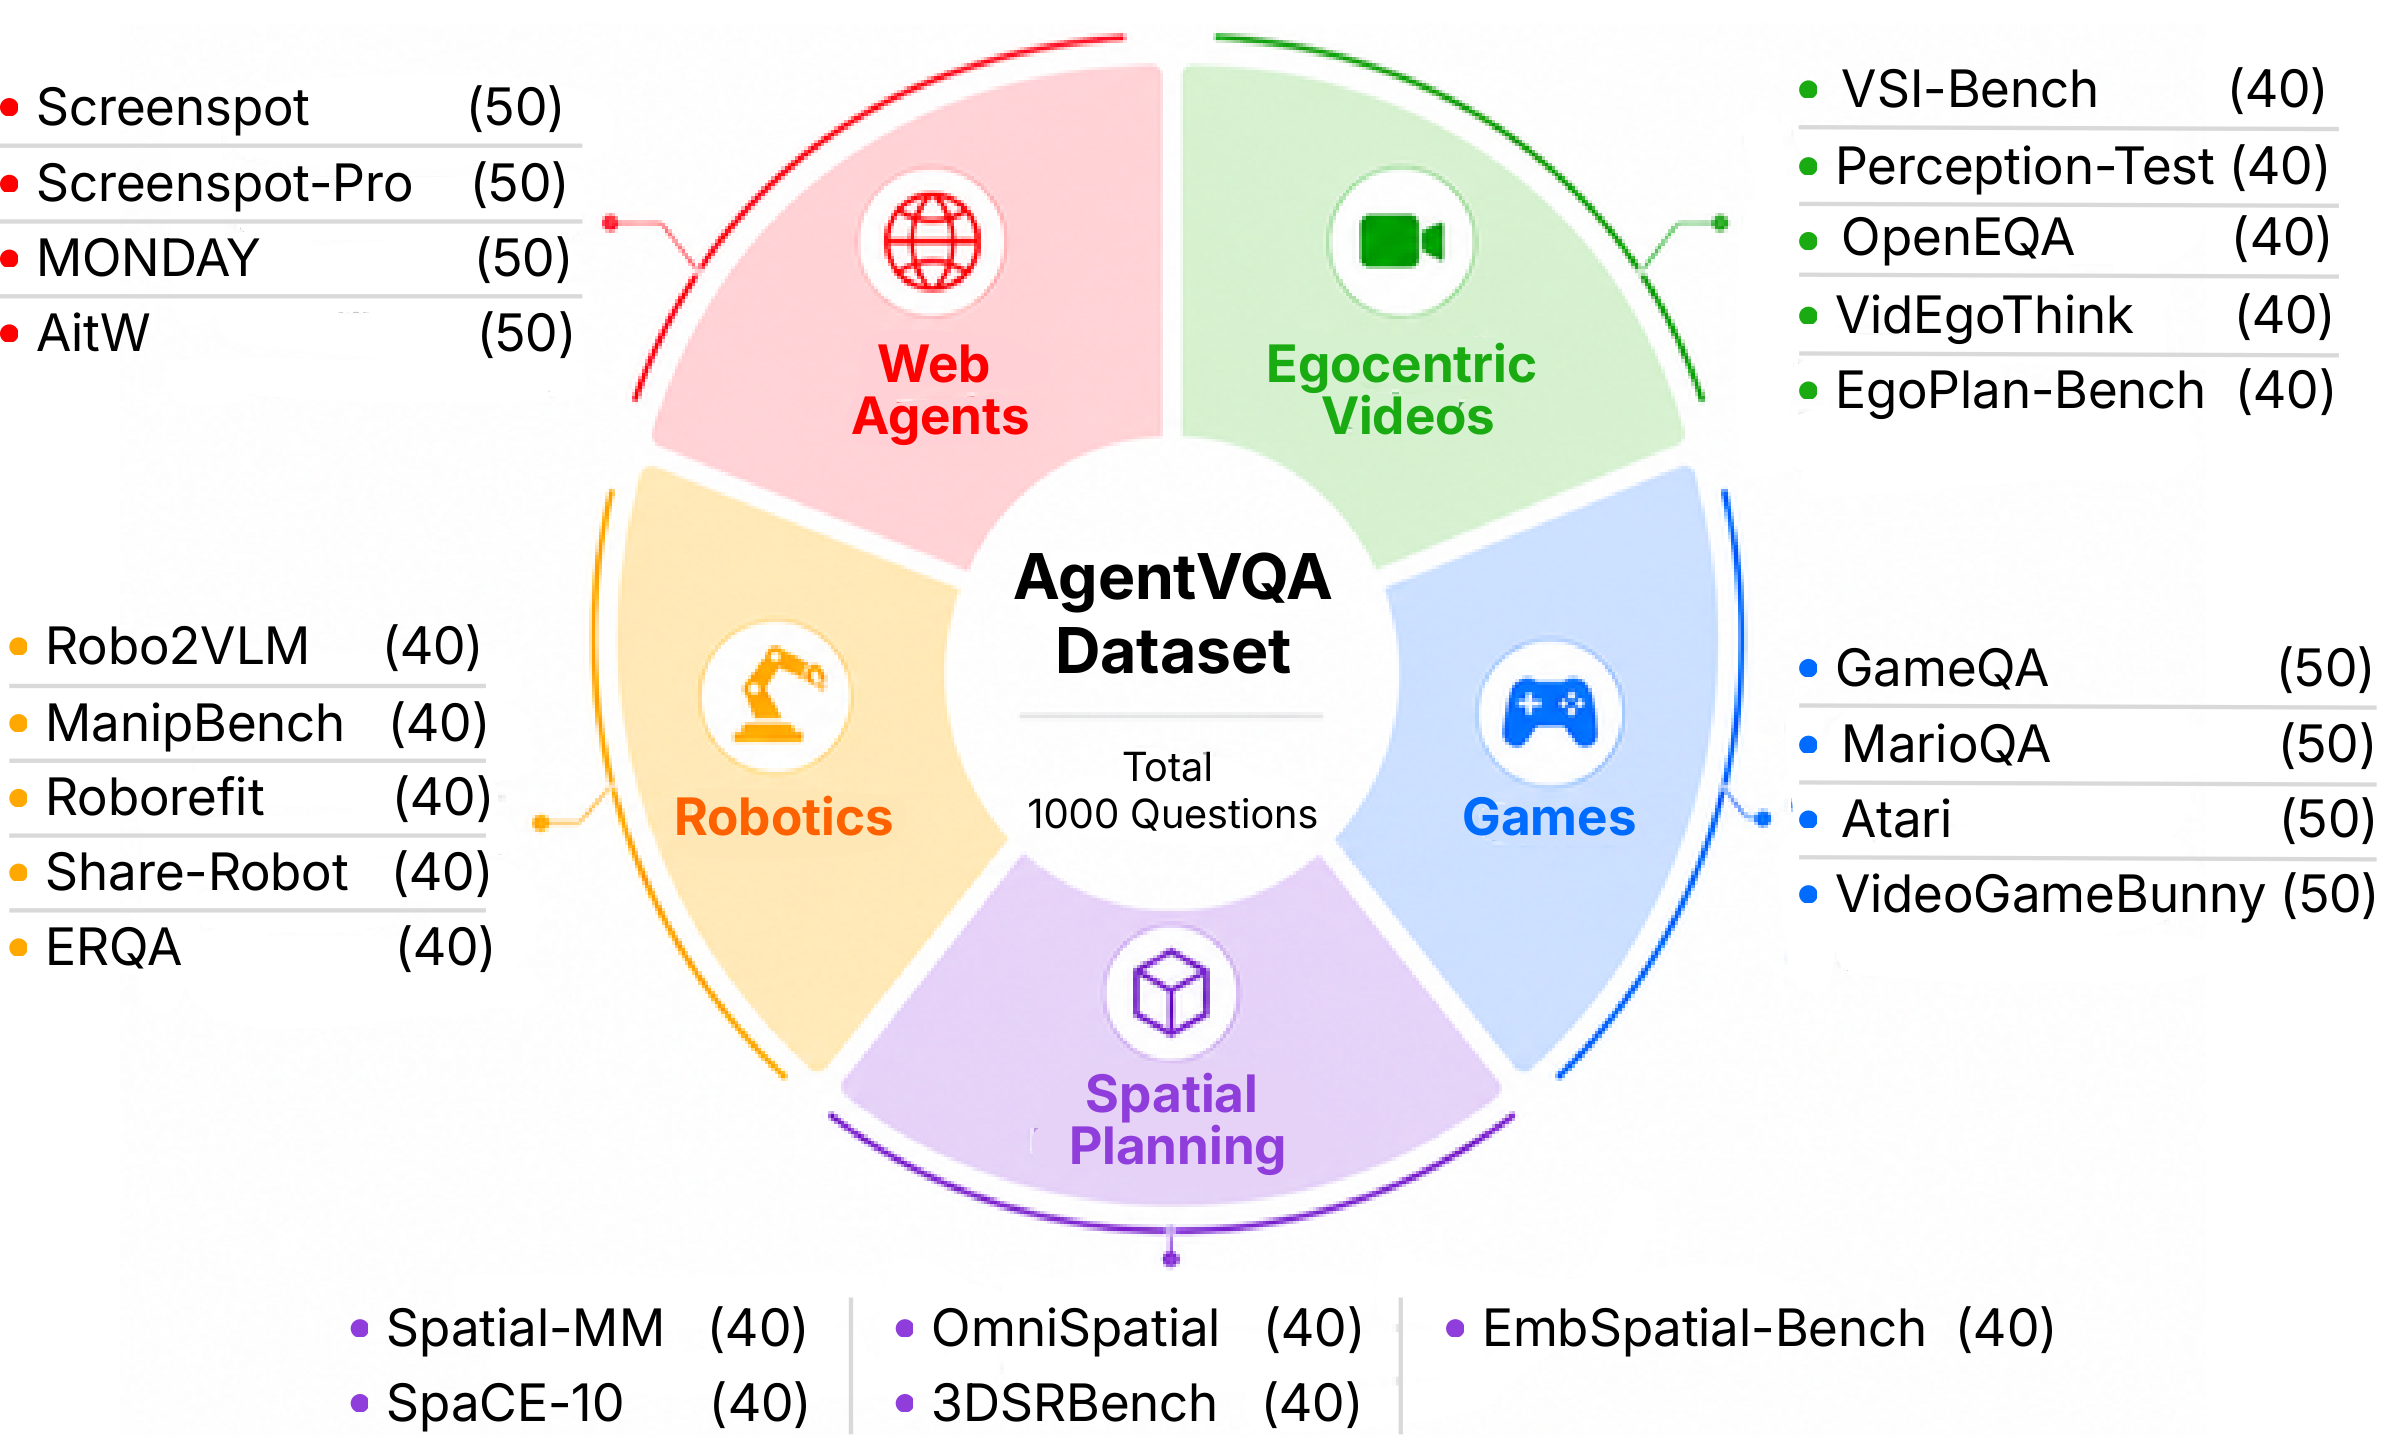
AgentVQA evaluates the visual understanding needed for goal-directed interaction: locating a button, interpreting an action, tracking a game state, or planning a route. It brings together 23 datasets across Web Agents, Egocentric Videos, Games, Spatial Planning, and Robotics in a common multiple-choice format.
The benchmark contains 1,000 human-verified questions, with 200 per domain. Questions use single images, image sequences, or videos, with episode goals and action histories where available. Across 22 evaluated model configurations, the best overall accuracy is 58.5%, achieved by Gemini 3.7 Flash.
Examples
One example from each of the 23 datasets. The correct answer is highlighted; model symbols indicate predictions.
Dataset curation
Questions undergo MCQ conversion, VLM screening, and manual checks for correctness, clarity, difficulty, and distractor quality.
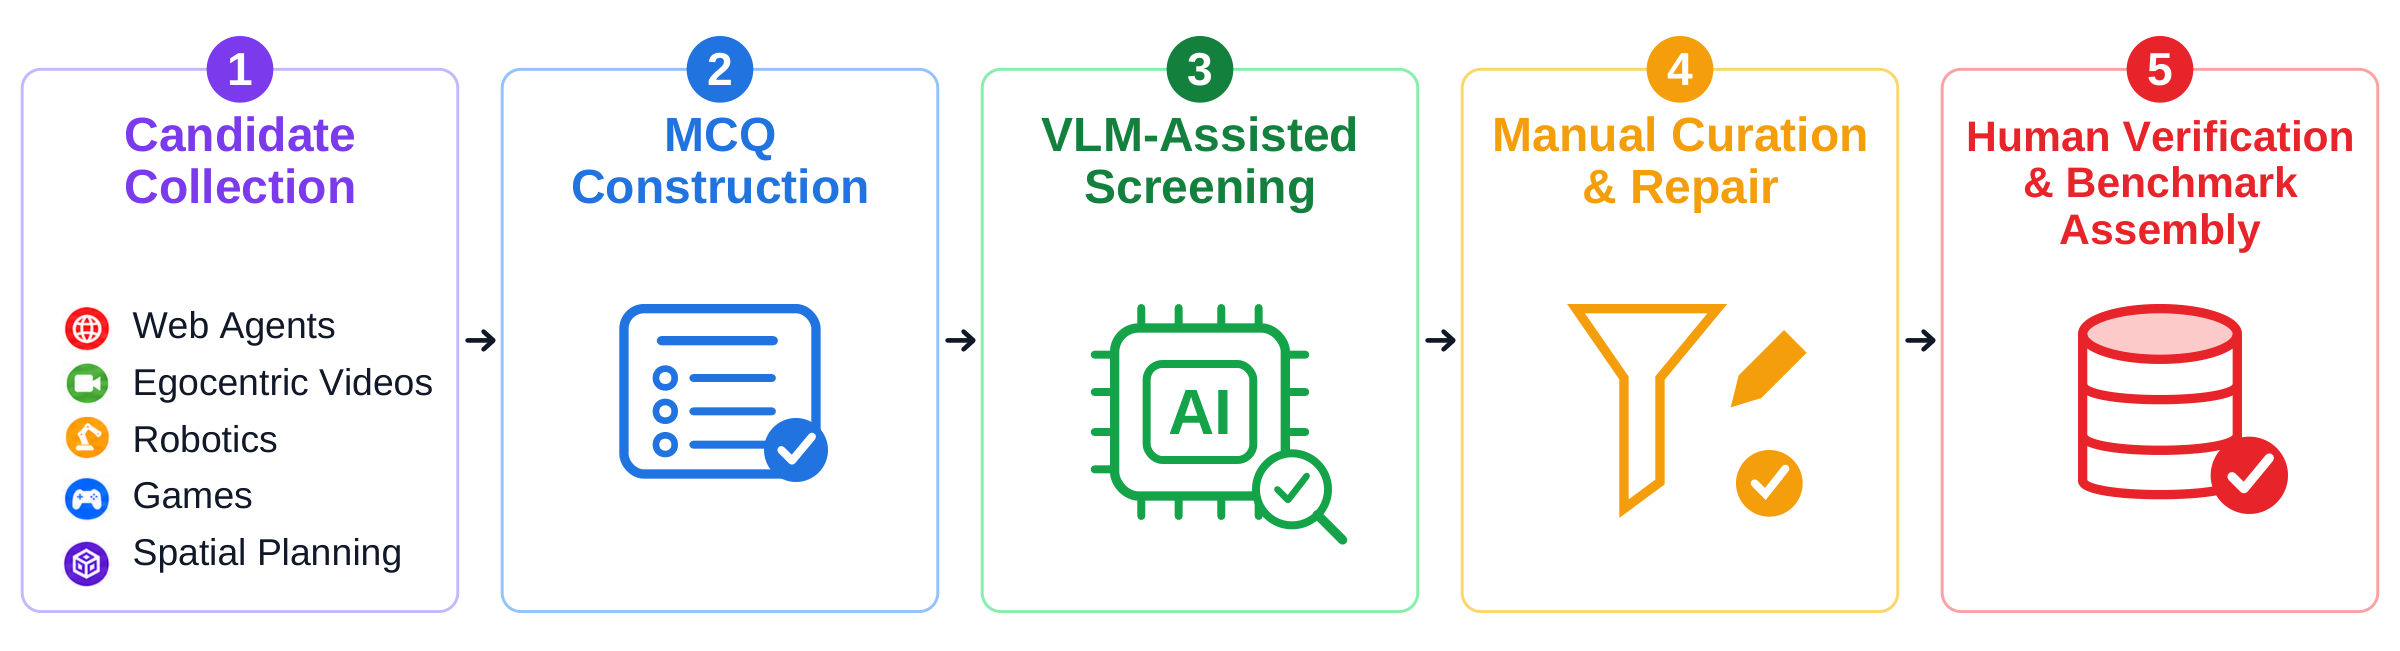
The final benchmark retains 22% of initial candidates. Each retained question is verified to have exactly one correct answer.
Key findings
- Model performance. Gemini 3.7 Flash achieves the highest overall accuracy at 58.5%. No single model leads every domain.
- Online correlation. AgentVQA Spatial Planning vs. SpatialWorld Physical: Spearman ρ = 0.895 across 12 shared models.
- Error modes. Grounding, motion perception, and spatial-state understanding are prominent failure categories.
Citation
If you find AgentVQA useful in your research, please consider citing:
@misc{gupta2026agentvqa,
  title={AgentVQA: A Unified Benchmark for Agentic Visual Understanding},
  author={Gupta, Advait and Konan, Sachin and Yin, Tom and Sarch, Gabriel and Liu, Zhuang},
  year={2026},
  url={https://openreview.net/pdf?id=MQinK5xoYM}
}